Harness Engineering for Self-Improvement
The idea of recursive self-improvement (RSI) can be traced to I. J. Good (1965), who described an “ultraintelligent machine” as a system capable of exceeding human performance in all intellectual activities and of designing superior machines to improve itself. Yudkowsky (2008) later used the term “recursive self-improvement” to refer to a particular feedback loop: an AI applies its current intelligence to enhance the cognitive machinery that generates its intelligence. In contemporary AI, this feedback loop may mean a model directly rewriting its own weights; more broadly, it can involve improving the training pipeline and the deployment system, which then supports a stronger successor model with better performance across economically valuable tasks. The pace of AI research progress has been shown to be drastically accelerated in frontier labs (Anthropic; OpenAI).
· 31 min read · Curated and presented by Arthur Sedek
The idea of recursive self-improvement (RSI) can be traced to I. J. Good (1965), who described an “ultraintelligent machine” as a system that exceeds humans in every intellectual endeavor and can design superior machines to enhance itself. Yudkowsky (2008) later used the term “recursive self-improvement” to denote a particular feedback loop: an AI applies its current intelligence to improve the cognitive machinery that generates its intelligence.
In modern AI, this feedback loop could mean a model directly rewriting its own weights, or, more broadly, improving the training pipeline and the deployment system. Those improvements can, in turn, produce a better successor model that performs more effectively across economically valuable tasks. Evidence suggests that the pace of AI research progress has accelerated substantially within frontier laboratories (Anthropic; OpenAI).
I emphasize the deployment system explicitly because the layer that connects a raw model to real-world context often matters as much as the model’s inherent capability (for example, evaluations immediately after pretraining). Deployment harnesses are a key part of this layer, as illustrated by successful coding-agent products such as Claude Code and Codex. A harness is the surrounding system that coordinates execution and determines how the model thinks and plans, invokes tools and takes actions, perceives and manages context, stores artifacts, and evaluates outcomes.
This post focuses specifically on research in harness engineering and its role in RSI. A large portion of recent work on auto-research, self-improving agents, and evolutionary program search can be framed around this theme. Other lines of research also align with the RSI vision, including model self-play, synthetic data, test-time training, and the broader motif of continual learning (for example, Yuan et al. 2024, Chen et al. 2024), Zhao et al. 2025, Choi et al. 2026)) but those directions are not the focus here.
Harness Design Patterns
Relative to early agent frameworks (often described as “agent = LLM + memory + tools + planning + action”), harness engineering adds workflow design (for example, loop engineering), evaluation, permission controls, and persistent state management. It extends beyond prompt templates and moves closer to runtime and software-systems design, specifically, how the model observes, acts, remembers, verifies its work, and improves.
Harness designs should be intentionally simple and broadly applicable to support generalization, likely drawing on established software-engineering practices so that they can benefit from prertaining knowlege. There is also a strong analogy between harnesses and operating systems. Like an OS, a harness should encapsulate complex logic while exposing a simple interface. Over time, configuration formats, tool interfaces, and related protocols may become increasingly standardized across the industry.
Pattern 1: Workflow Automation
A central design for automation is defining a workflow in which the model can operate, test, and iterate. Karpathy’s autoresearch repository (https://github.com/karpathy/autoresearch) is a clear example of how to build such a workflow. A typical workflow follows a goal-directed loop: plan, execute, observe or test, improve, and execute again until the goal is met. Along the way, the process may proactively query users to clarify task specifications or preferred execution styles.
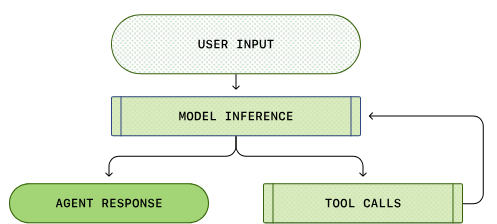
(Image source: OpenAI codex agent post)
The workflow graph also highlights that the model should analyze its own trajectories and failure cases, then iterate via an “agent runtime” rather than relying on a fixed prompt template.
Pattern 2: File System as Persistent Memory
A common pattern in long-horizon agent systems is to keep control logic simple while supporting rich state and artifact management. A harness should not attempt to carry the entire workflow and all logs in the model’s context. Instead, it should maintain durable state in files. During long-horizon agentic rollouts, artifacts such as experiment logs, code diffs, paper summaries, error traces, and prior rollout trajectories frequently grow far beyond the context window the model was trained to handle.
The ability to read, write, and edit the file system (often via bash commands) is a foundational LLM skill. As a result, implementing persistent memory through files naturally benefits from improvements in core model capability.
Pattern 3: Sub-agent and Backend Jobs
A harness can spawn multiple subagents to run in parallel and can also supervise backend jobs. This is useful when the main agent must explore multiple hypotheses, run concurrent experiments, or delegate isolated subtasks without contaminating the main context. The parent agent therefore needs a lightweight process manager that can launch jobs, inspect logs, terminate failed runs, and integrate results back into the main agent thread.
The essential design decision is to keep parallelism explicit and observable. When subagent outputs exist only in ephemeral chat context, they quickly become obselete and effectively hidden. When they are stored as files, logs, and status records, the model can recover after interruptions and can reason over its own execution history.
Case study: Coding Agent Harness
The core interface for mainstream coding agents has largely stabilized across Claude Code, Codex, OpenCode, and Cursor-style agents. These systems commonly use a loop of the following form:
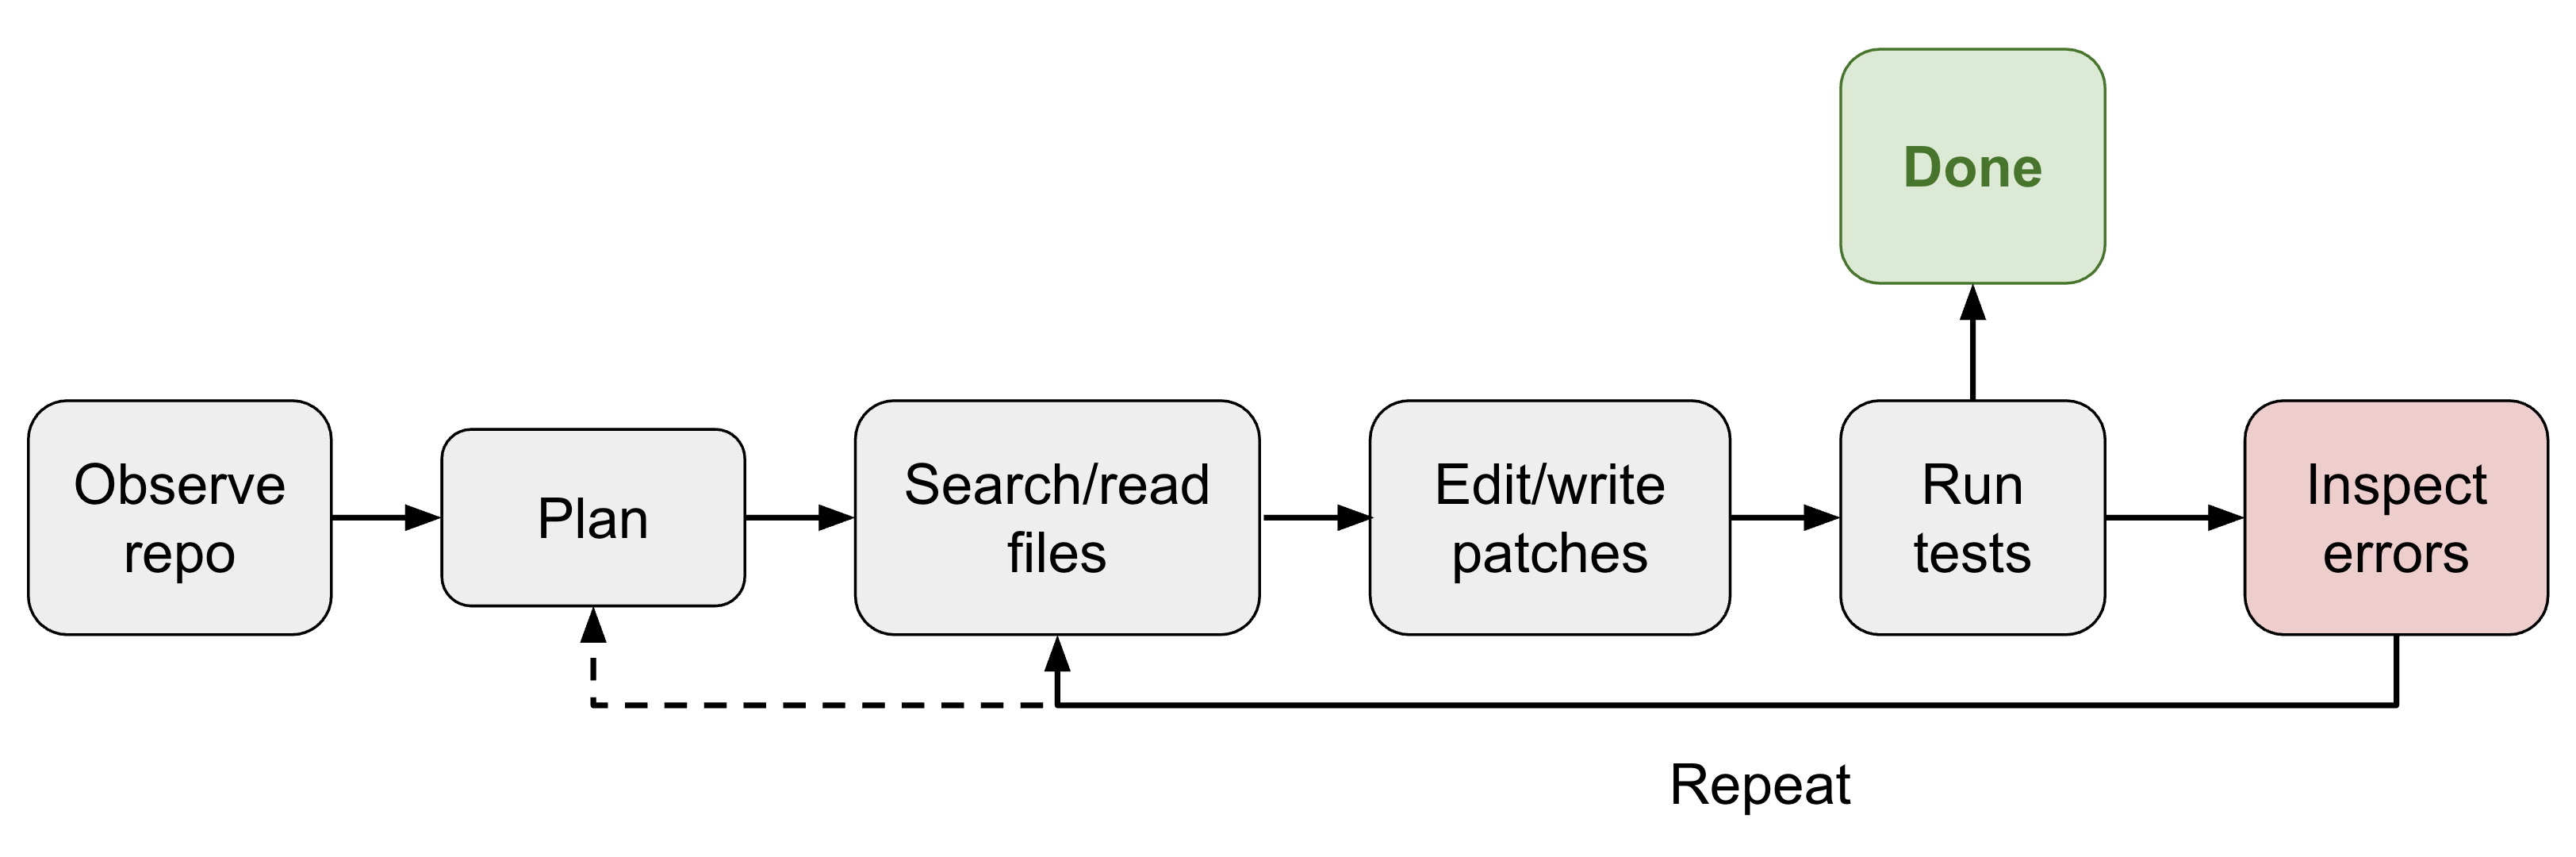
Given access to a tool set, a coding agent can develop and debug issues within a repository in a way that parallels how human developers operate with IDE support.
(Not a comprenhensive list; shown for demonstration. Read this if interested.)
| Group | Tool definitions |
|---|---|
| File system | - File discovery: glob, grep, ls- File read: read, read_many- File modification: write (a whole new file); edit (string exact-match replacement); multi_edit; apply_patch (applies a structured patch/diff) |
| Shell execution | Run commands: bash, PowerShell |
| IO | lsp, git tools like git_status, git_diff, git_commit |
| External context | MCP tools, Skills |
| Web search | web_search, web_fetch, browser tools |
| Artifacts | Read docs, images; generate HTML, images |
| Backend processes | Such as: CronCreate, CronDelete, CronList |
| Agent delegation | Such as: spawn_agent, resume_agent, wait_agent, list_agents, close_agent, interrupt_agent, etc. |
Harness Layer vs Core Intelligence?
Forecasting how heavily RSI will ultimately depend on harness engineering is difficult, but a near-term RSI trajectory is unlikely to begin with models directly rewriting their own weights. My view of a practical near-term path is as follows:
- Harness engineering will trend toward meta-methodology (that is, improving the machinery that produces better answers, not merely improving the answers themselves). The harness becomes an explicit optimization target, with fewer heuristic rules and more general-purpose mechanisms.
- As a consequence, mature harnesses enable auto-research for model self-improvement loops, and smarter models prevent harnesses from becoming overengineered, helping keep the overall system sustainable.
Over time, many harness improvements may be internalized into core model behavior, but the interface to external context and tools should remain. A weaker form of this pattern has already appeared in prompt engineering: hand-crafted prompt tricks became less central as instruction tuning and model reasoning improved, but the need to specify goals, constraints, context, and evaluation did not disappear.
Harness Optimization
The evolution of what the harness system optimizes can be sketched as: instruction prompts → structured context → workflow → harness code → optimizer code. As models grow more capable, optimization targets tend to become more complex, and methods tend to become more generic.
Context Engineering
Naively appending every tool response and model generation into context can quickly become unmanageable as the horizon of agentic work lengthens. Context management is a layer that constructs a more structed and concise context for the LLM while also managing persistant states. Long-context research will undoubtedly continue to advance, but at present, long-context intelligence and context engineering sometime intertwines.
Agentic Context Engineering (ACE; Zhang et al. 2025) treats context as an evolving playbook rather than a continuously growing prompt. It uses three components to maintain a playbook composed of bullet points, each with an identifier and a description.
- Generator: produces task trajectories, with reference to bullet points.
- Reflector: distills insights from successful and failed trajectories.
- Curator: updates the structured context with incremental, itemized entries.
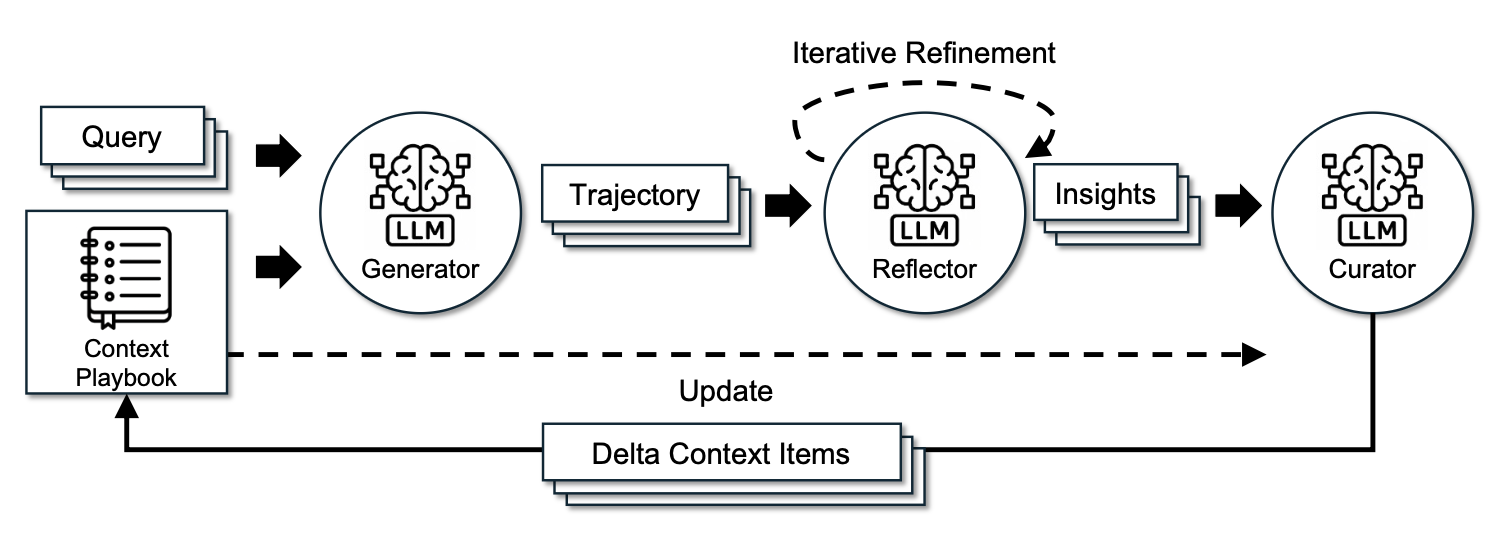
To reduce context collapse and mitigate brevity bias during iterative rewrites, a key ACE design choice is that the curator does not rewrite a single, monolithic prompt blob. Instead, it outputs a set of structured, itemized bullets of the form (identifier, description). These bullets are merged into a structured context logbook using deterministic logic. The context items are periodically refined and deduplicated.
ACE’s ability to learn insights from rollouts is a step toward self-managed memory, but its update rules and overall workflow remain handcrafted. To move closer to a self-improving loop, Meta Context Engineering (MCE; Ye et al. 2026) separates the mechanism (how context is managed) from the artifact content (what the context contains). It runs skill evolution at the meta-optimization level and context optimization at the base level.
An MCE skill $s \in \mathcal{S}$ defines a context function $c_s=(\rho_s,F_s)$ and maps an input $x$ to context $c = F_s(x;\rho_s)$, where:
- $\rho_s = \{\rho_1,\dots,\rho_m\}$ are static components (prompts, knowledge bases, code libraries).
- $F_s = \{F_1,\dots,F_k\}$ are dynamic operators (search, selection, filtering, formatting).
The bi-level optimization searches for the best context $c_s^*$ given skill $s$ on training data, while an outer loop identifies the optimal skill that yields the best validation-set performance:
The skill database records the history of prior skills, context functions, and evaluation metrics $\mathcal{H}_{k-1} = \{(s_i,c_i,J_i^\text{train}, J_i^\text{val})\}_{i=1}^{k-1}$. A meta-level agent performs agentic crossover over earlier skills to produce a new skill for a task $\tau$: $s_k=\text{crossover}(\tau,\mathcal{H}_{k-1})$.
A base-level context engineer then executes the skill $s_k$ and learns the context function from rollout feedback $\mathcal{R}_k$, guided by the current skill: $c_k=\text{engineer}(\tau,s_k;c_{k-1}^*,\mathcal{R}_k)$.
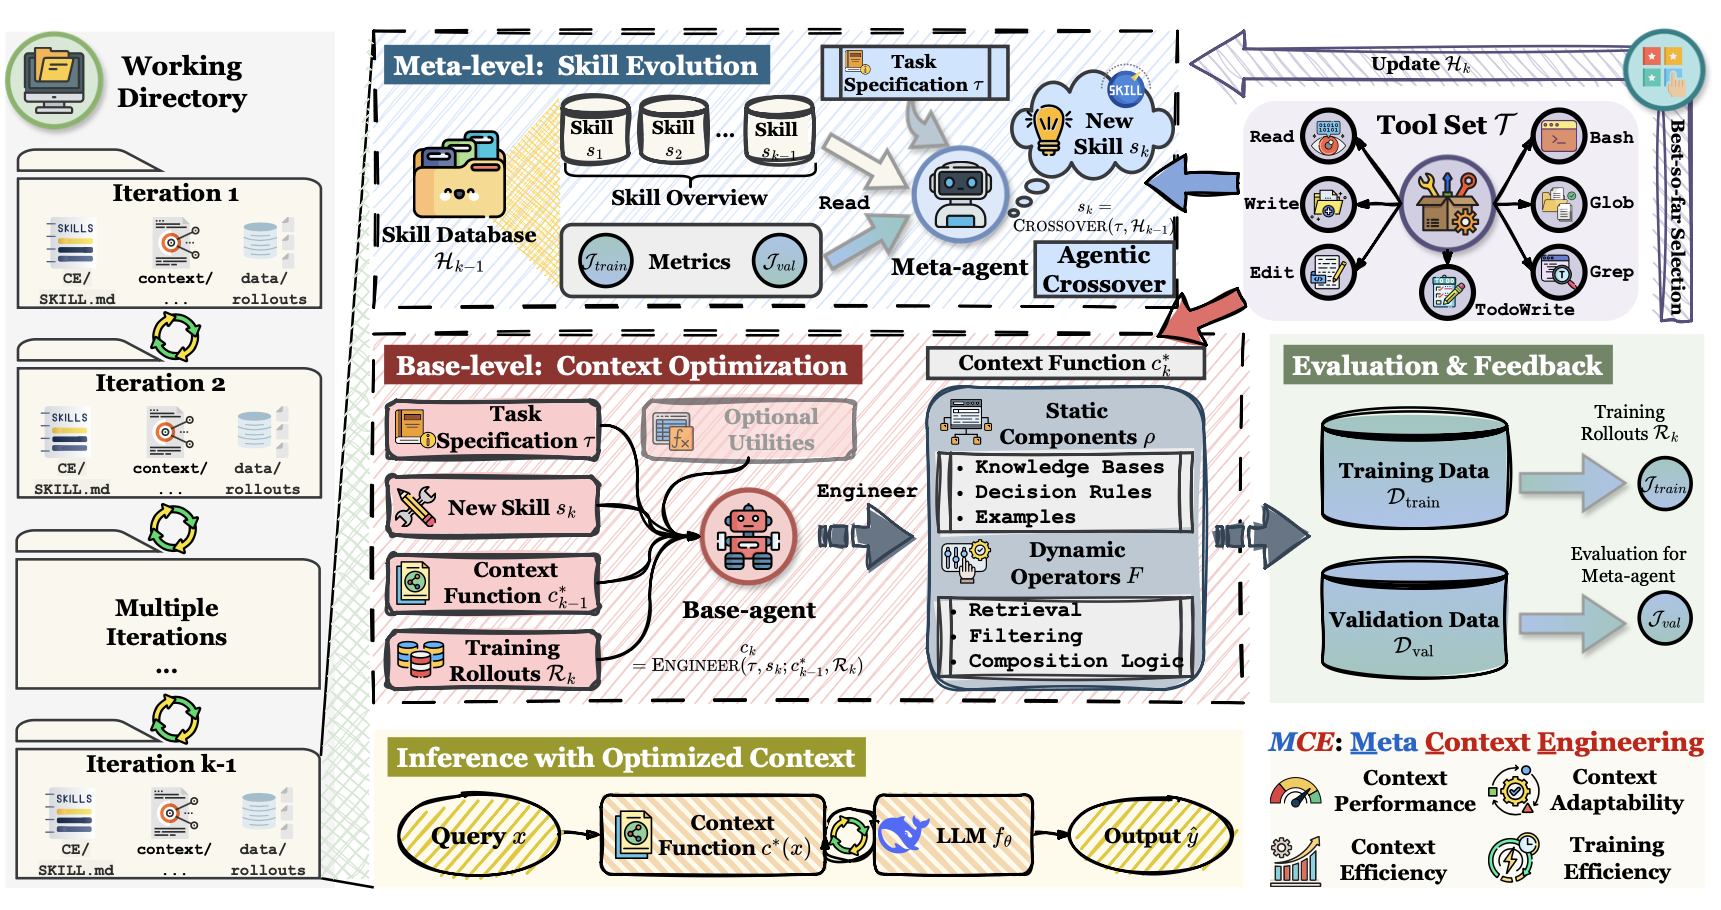
MCE does not impose heuristic structuring rules in the way ACE does. Instead, it uses free-form skills to store the most important knowledge for a task, and it co-evolves the skill and the skill-conditioned context iteratively. In implementation terms, a context function $c$ is instantiated as a set of files in a dedicated directory, containing both static components (skill.md) and dynamic components (context and data rollouts). Both meta-level and base-level optimization run in agentic coding envs with a standard tool set,
Meta-Harness (Lee et al. 2026) goes one level further: the optimized object becomes the code that determines and optimizes which information should be stored, retrieved, and presented to the model. The “Meta-” prefix indicates that it is a harness intended to optimize harnesses.
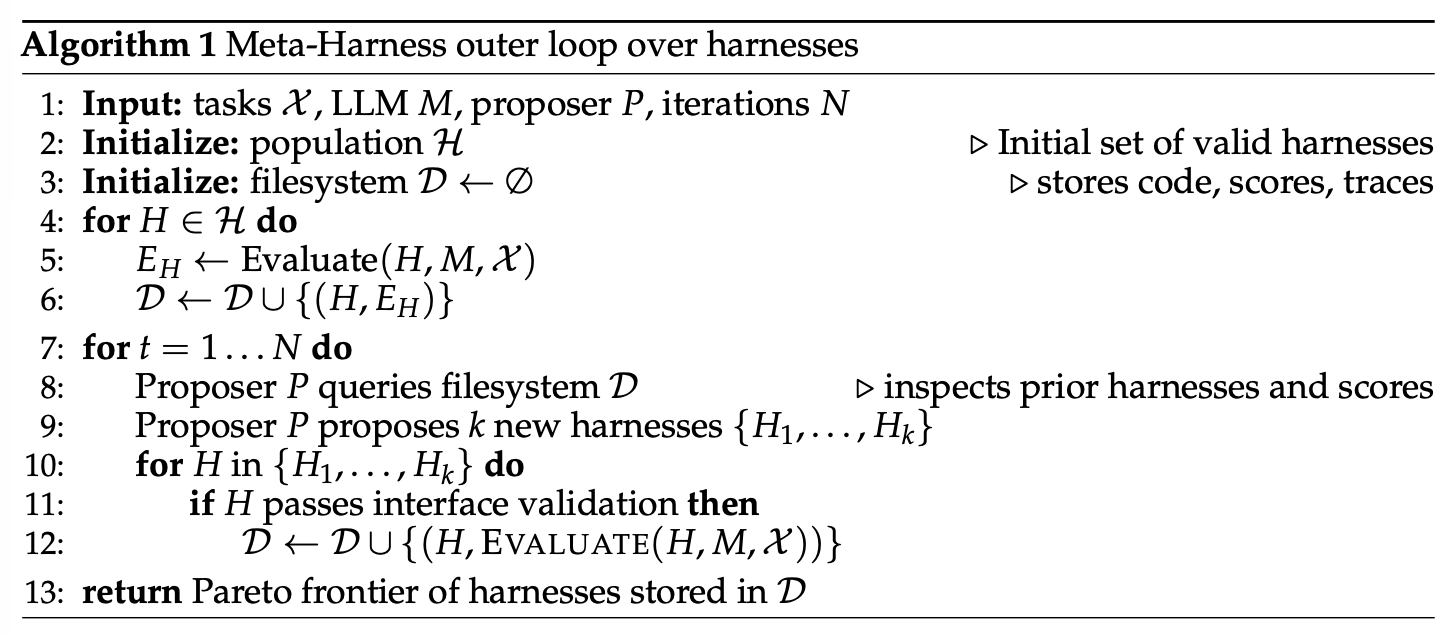
In Meta-Harness, the proposer that generates a new harness is itself a coding agent, and the final output is a set of harness candidates on the Pareto frontier.
- The complete execution history is available through the file system, so the coding agent can use commands such as
greporcatto review it rather than forcing everything into a single prompt context. - Each proposed harness is represented as a directory in the file system that contains its own source code, scores, rollout trajectories, and state updates.
- The mete-harness loop iteratively generates new harnesses, and only those that meet qualification criteria are retained.
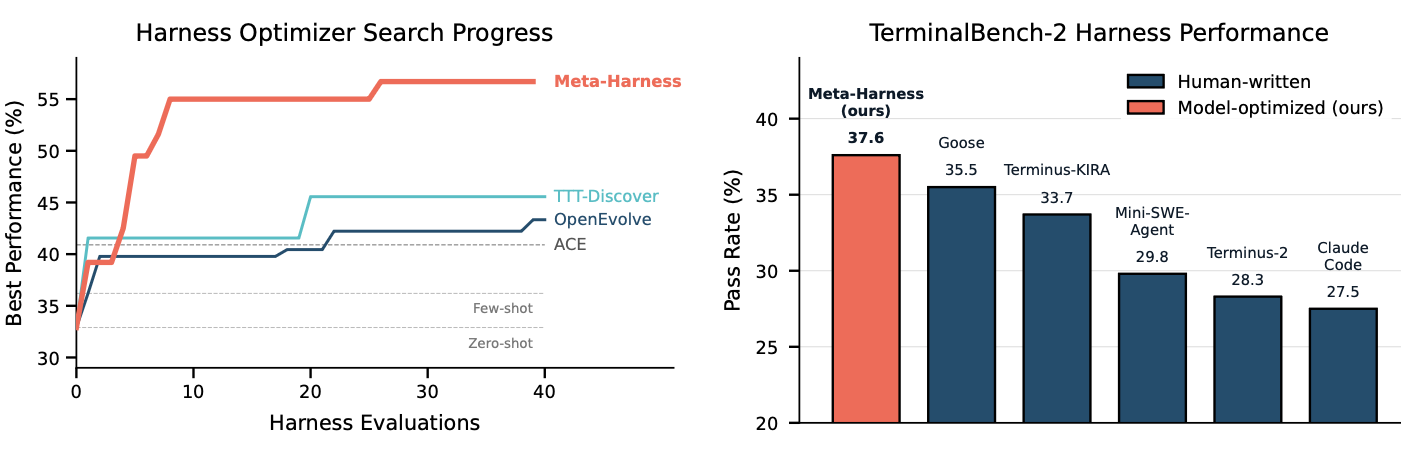
The core takeaway remains straightforward: once harness design is turned into an executable search space, a strong coding agent can exploit the same space of designs that human engineers use.
Workflow Design
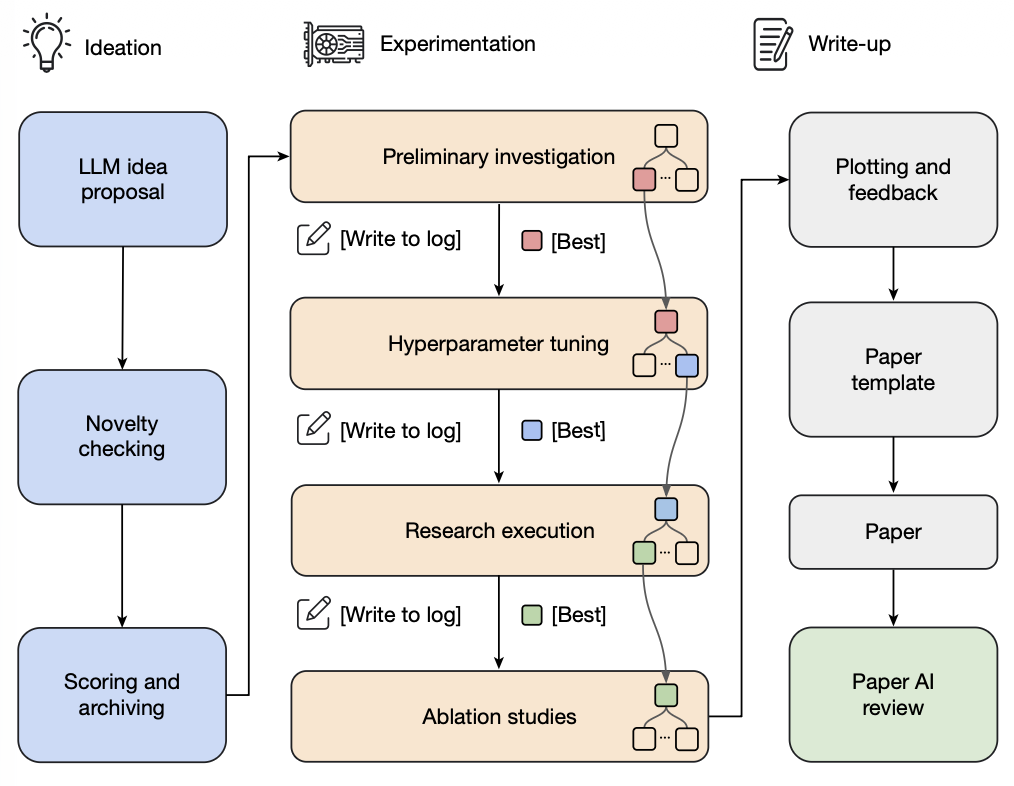
In harness engineering, workflow design can be manually crafted by domain experts. In auto-research, for example, multiple frameworks have been proposed and evaluated. The AI Scientist system (Lu et al. 2026) implements a pipeline that proposes research ideas, writes code, runs experiments, analyzes results, writes a manuscript, and conducts peer review. Meng et al. (2026) center ScientistOne on verifiability as the primary design constraint: every claim (citation, numerical, methodological, conclusion) must be traceable to an evidence source and is audited through Chain-of-Evidence checks.
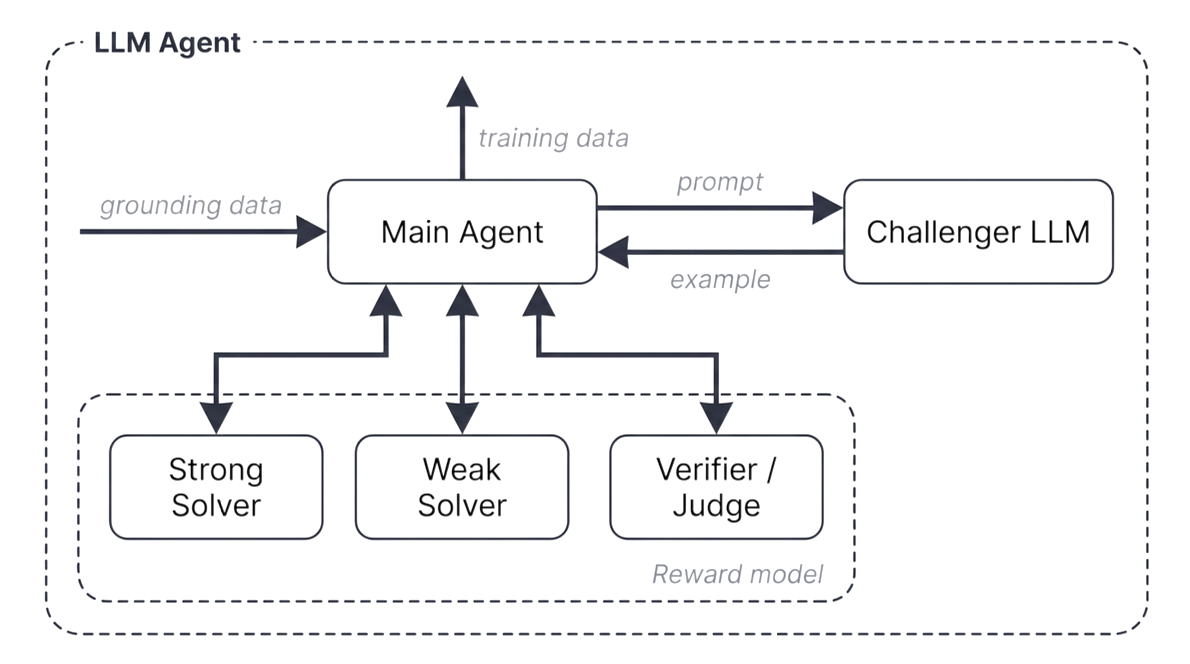
The Autodata agent (Kulikov et al. 2026) is intended to function as a data scientist for generating training and evaluation datasets. Its main agent coordinates a challenger that proposes problems, a weak solver, a strong solver, and a verifier/judge. The goal is to synthesize tasks at a “just right” level of difficulty, meaning the strong solver succeeds while the weak solver fails.
In Autodata, the challenger prompt is iteratively updated based on feedback from the solvers and the verifier. A limitation is that the synthesized tasks are used to fine-tune weak solvers but not strong solvers. If the loop cannot iteratively improve the strong model, the process resembles indirect distillation over a generated prompt distribution and carries a weaker RSI flavor.
The workflow design space is enormous. It is therefore natural to treat workflow design as a search problem and to expect that algorithms, not only manual engineering, can discover strong solutions. In this spirit, Automated Design of Agentic Systems (ADAS; Hu et al. 2025) formulates agent design as an optimization problem, namely, “meta-agent search,” where a meta-agent proposes new agentic-workflow designs.
- Initialize an archive of agentic workflows with simple agents, such as CoT and self-refine.
- Ask a meta-agent to program new agents entirely in code, drawing inspiration from existing solutions in the archive.
- The meta-agent first produces a high-level description of the new workflow, then implements it in code.
- The draft program then undergoes two self-refine steps (that is, ask the model for feedback, then ask the same model to refine previously generated outputs using that feedback; Madaan et al. 2023) performed by the meta-agent to check novelty.
- Evaluate each new candidate and add successful workflows back into the archive.
- Repeat steps 2-3 until the maximum number of iterations is reached.
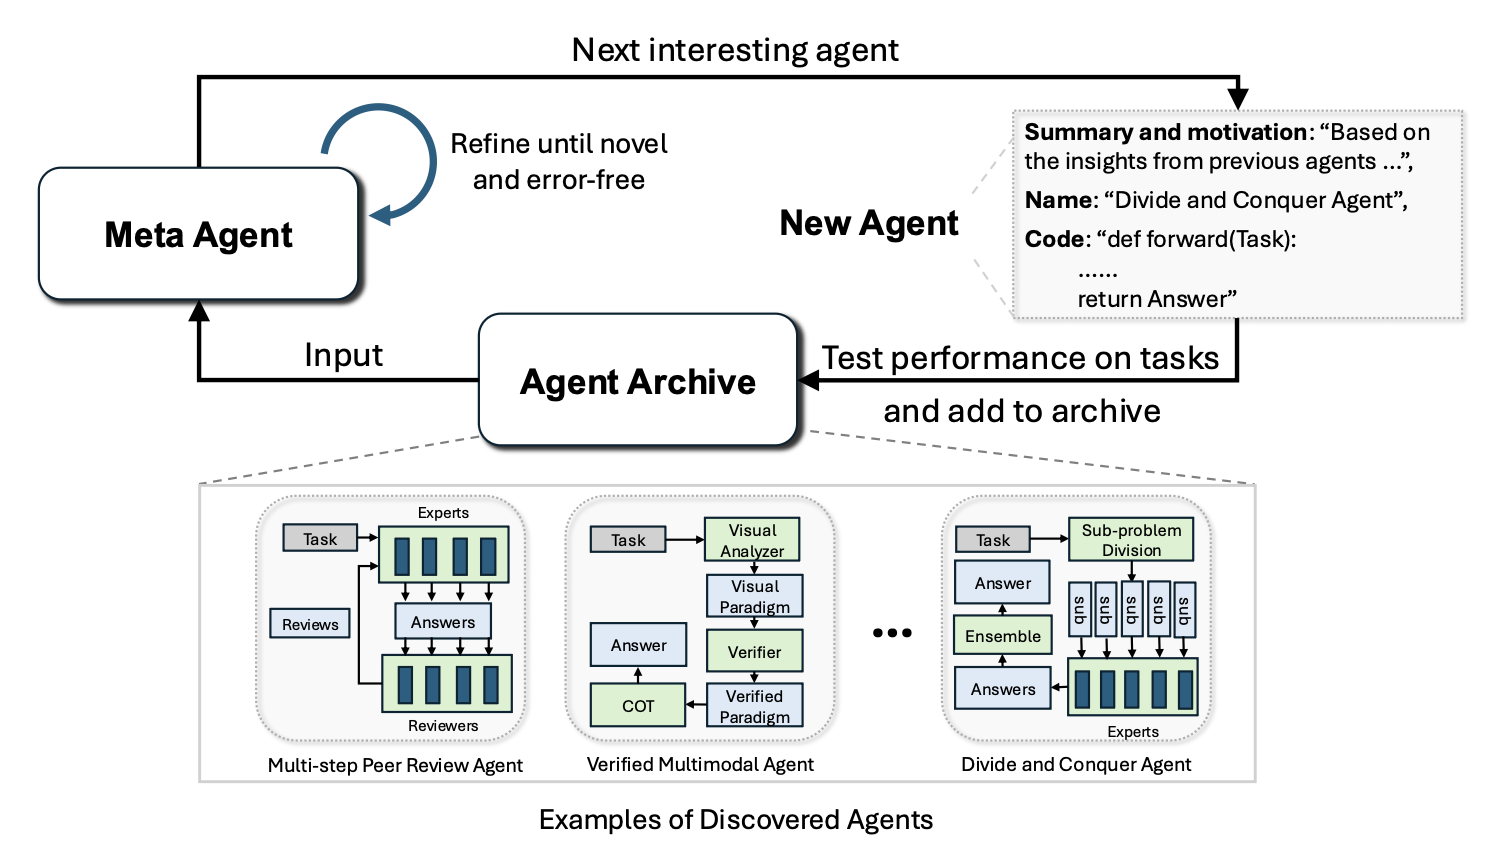
(Image source: Hu et al. 2025)
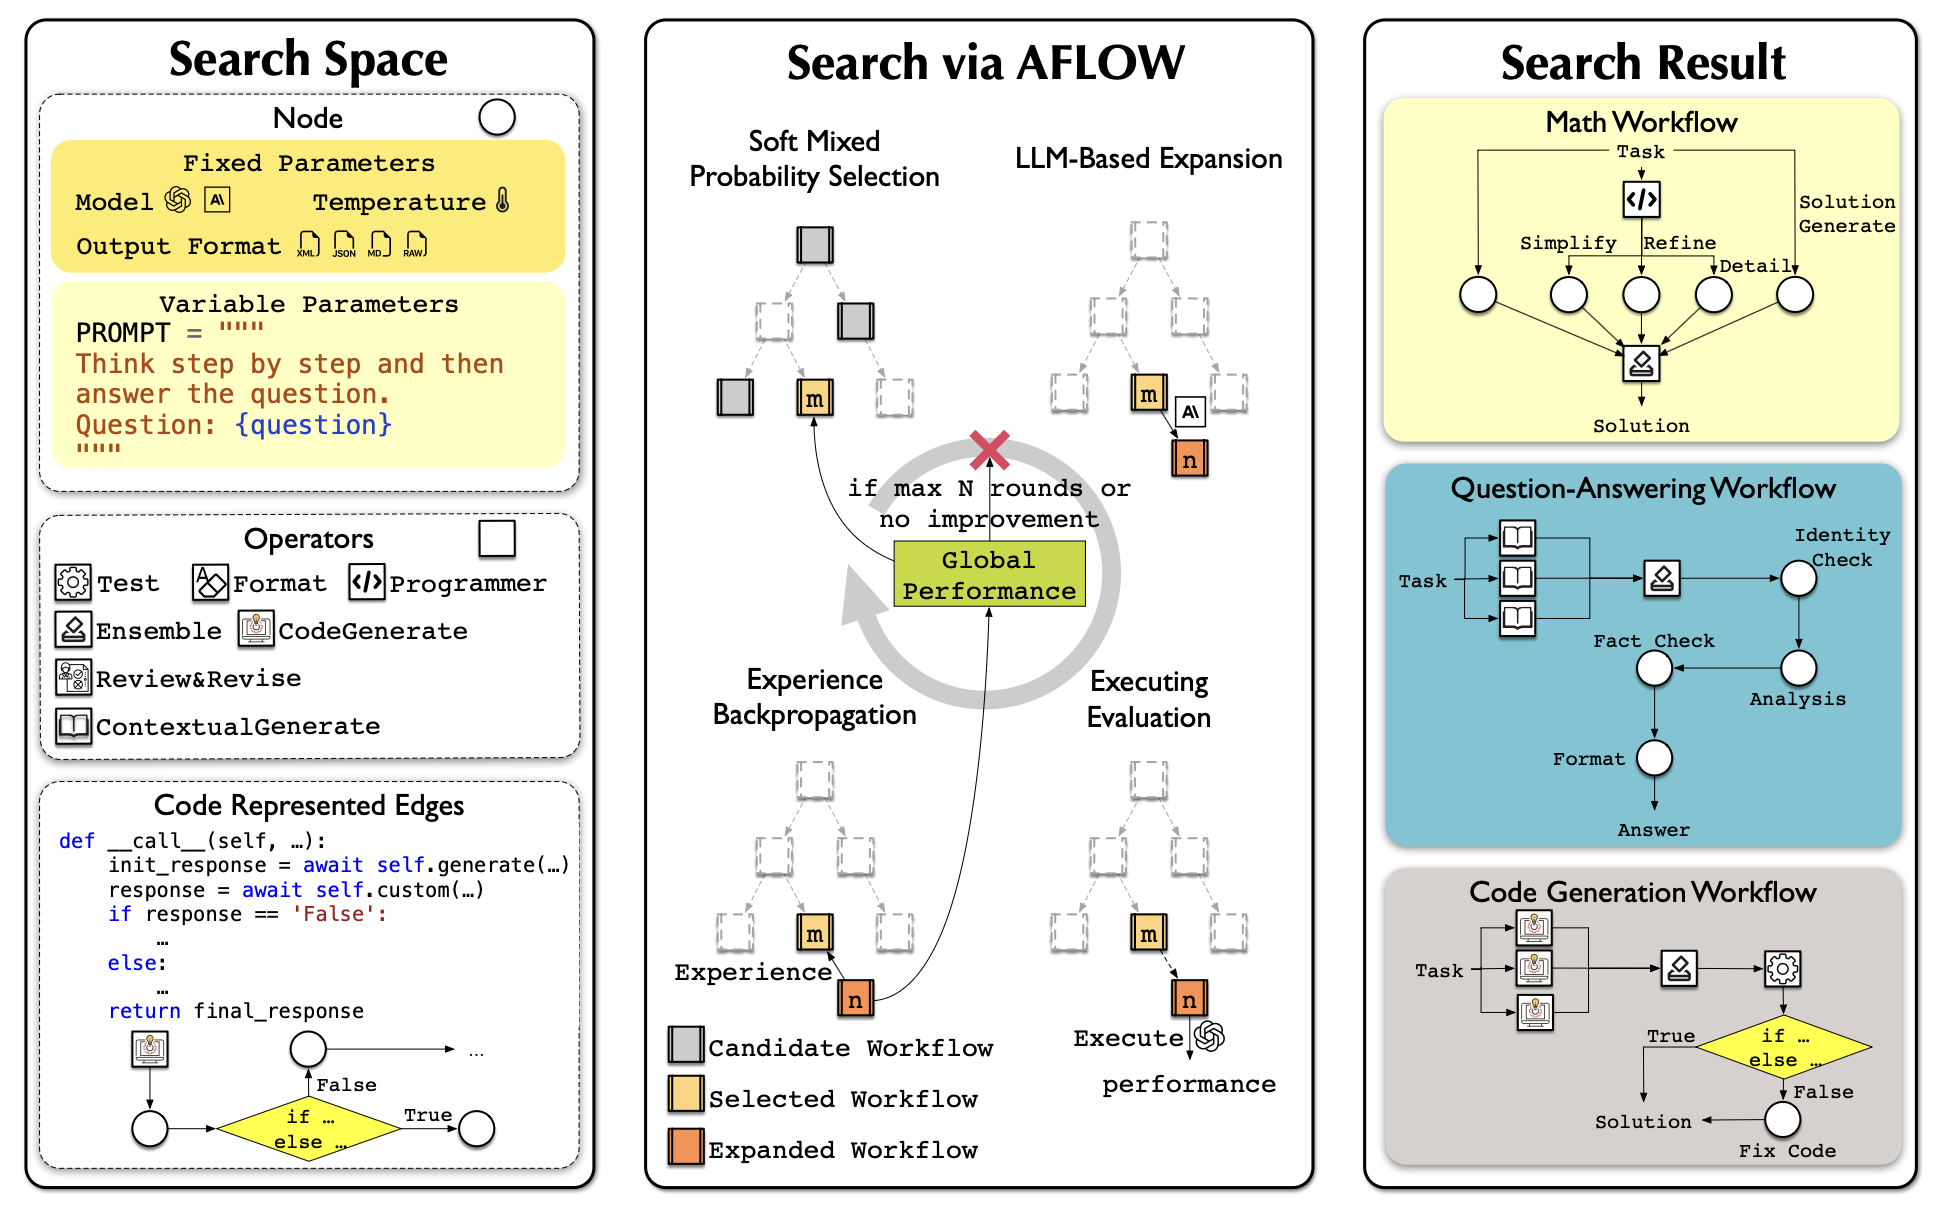
AFlow (Zhang et al. 2025) represents an agentic workflow as a graph: nodes correspond to LLM-invoking actions, and edges implement logical operations in code. Workflow optimization is driven by MCTS (Monte Carlo Tree Search):
- Initialize the starting workflow $W_0$ in the tree using a template.
- Select a workflow node using a soft mixture of score-based selection and uniform exploration.
- Expand the node by asking an LLM to generate a modified workflow conditioned on evaluation performance.
- Execute and evaluate the new workflow.
- Add it back into the tree if it improves performance within a budget of $N$ rounds.
- Repeat steps 2-5 and stop when the top-$k$ average score plateaus or when the budget is exhausted.
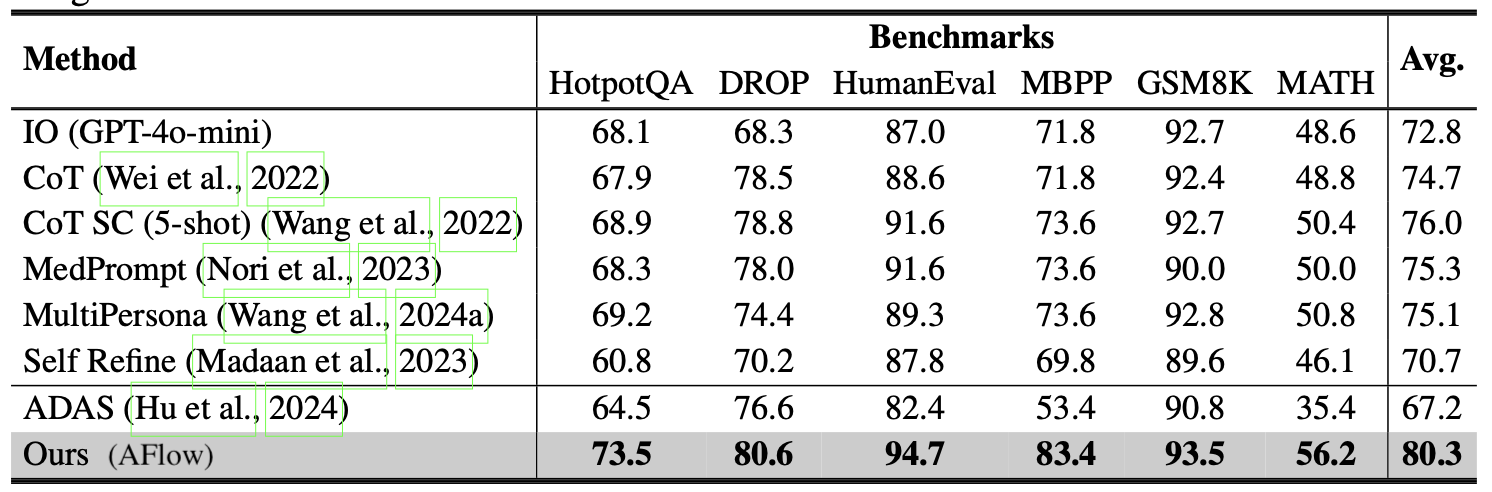
AFlow experiments on QA, code, and math tasks showed meaningful gains over manually designed workflows and over ADAS.
Self-Improving Harness
Context engineering and workflow design are each only one component of a harness. In practice, the full design space includes context-management logic, workflow, permissions, and many additional elements that must be optimized together. As suggested by work such as Meta-Harness, ADAS, and AFlow, ✨code✨ functions as a universal language for defining programs and systems. Put simply, a harness is code that specifies how prompts, tool calls, subagents, control flow, memory, and workflow logic operate together. If an LLM can optimize the code that executes agents, it can explore a much larger design space than is available through hand-written prompts alone.
Self-Taught Optimizer (STOP; Zelikman et al. 2023) is an early example of recursive improvement in scaffolding. A seed improver $I_0$ at step $t=0$ takes an initial solution $s$, a utility function $u$, and a black-box language model $M$, then produces an improved solution $s’$, namely, $s’ = I(u, s; M)$. STOP’s objective is not to directly improve $s$, but to improve the improver $I$ itself.
First, define the meta-utility as the mean utility of an improver function $I$ over a set of downstream tasks $\mathcal{D}$:
Because improving the improver is itself an optimization problem, a new version of $I_t$ can be produced recursively from $I_{t-1}$’s performance (as measured by meta-utility) via a self-improvement update:
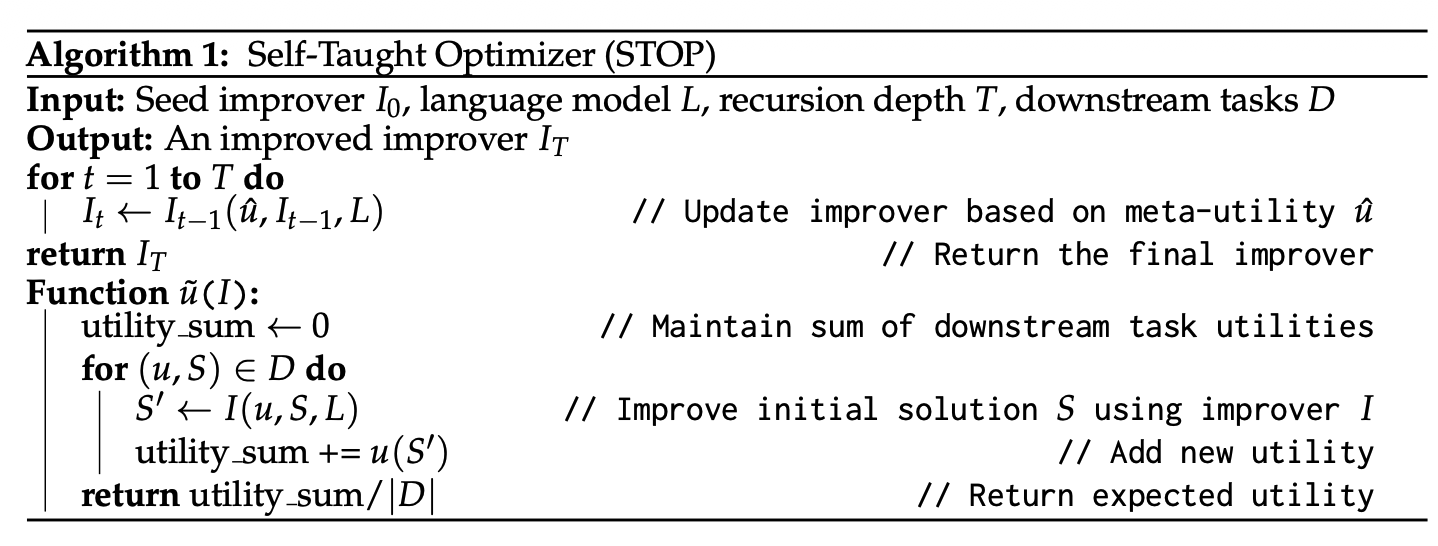
In experiments, the improved improver discovered a range of strategies, including genetic algorithms, decomposing and improving subcomponents, multi-armed prompt bandits, simulated annealing, temperature variation, and beam or tree search. This parallels the idea that a harness workflow can itself be represented as an object subject to optimization.
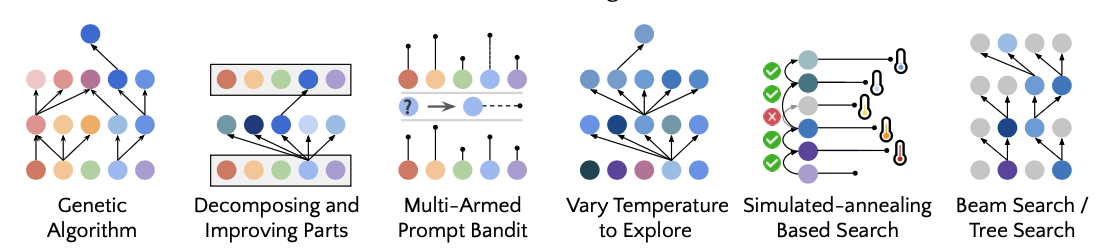
A cautionary finding in Zelikman et al. (2023) is that, across iterations, STOP increased mean downstream performance when paired with GPT-4 but degraded performance with weaker models such as GPT-3.5 and Mixtral. Recursive structure by itself is insufficient. The base model must be capable enough to improve the mechanism. This suggests that harness improvement can enable more effective deployment, but intelligence remains the core driver.
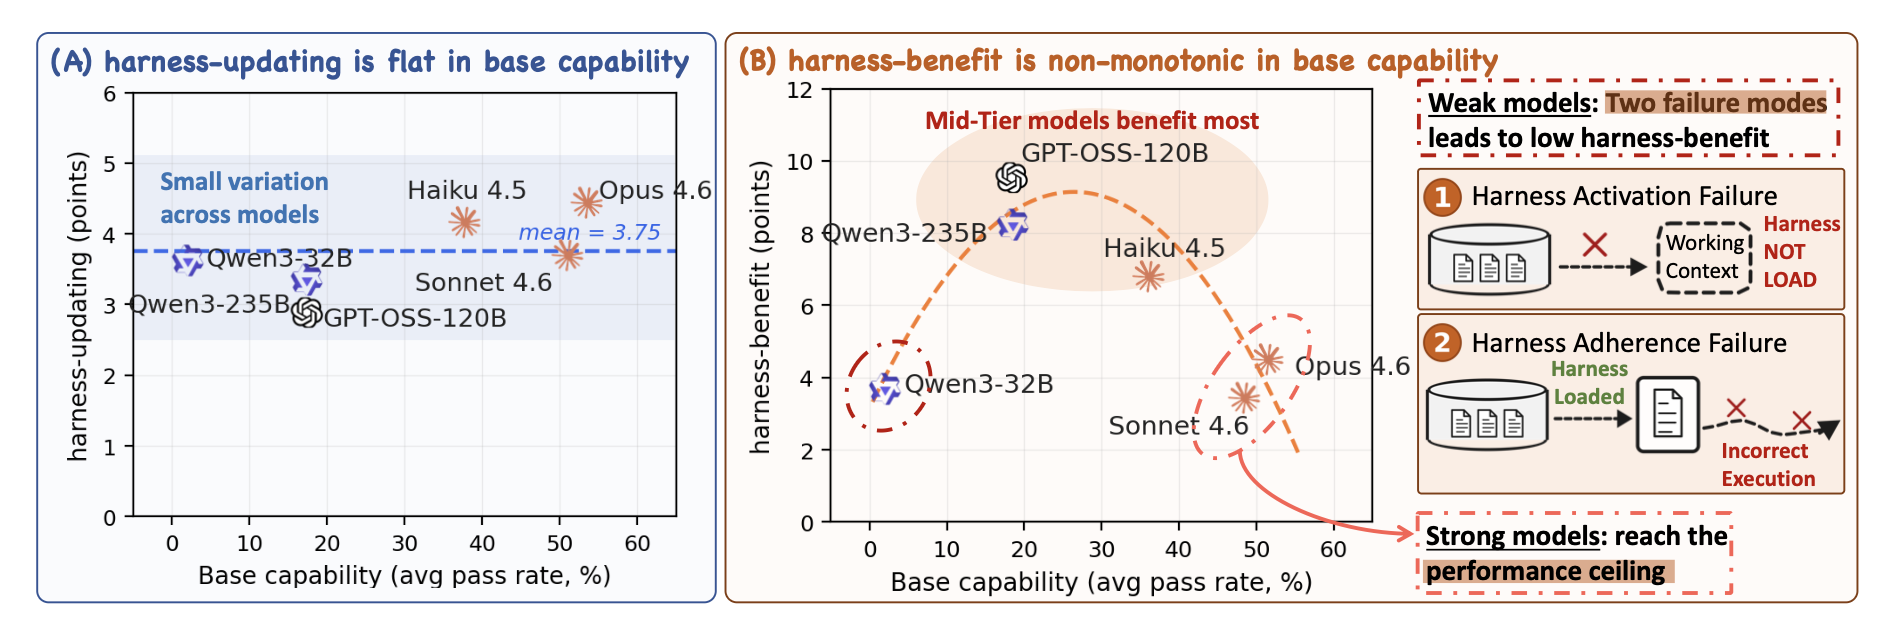
Lin et al. (2026) examined how harness evolution depends on model capability in more details. They separated two axes: (1) harness-updating, the ability to produce useful harness edits, and (2) harness-benefit, the ability to exploit an updated harness to solve tasks more effectively. Notably, in their experiments, models spanning sizes and core intelligence levels, from Qwen3.5-9B to Claude Opus 4.6, showed similar harness-updating capability. The 9B harness proposer/evolver could write a skill procedurally isomorphic to Opus. However, to benefit from a harness, a model must invoke skills and tools correctly and at the right time, and it must be strong at long-horizon instruction following.
A more recent approach, Self-Harness (Zhang et al. 2026), uses LLM agents to improve their own harness through a propose-evaluate-accept loop.
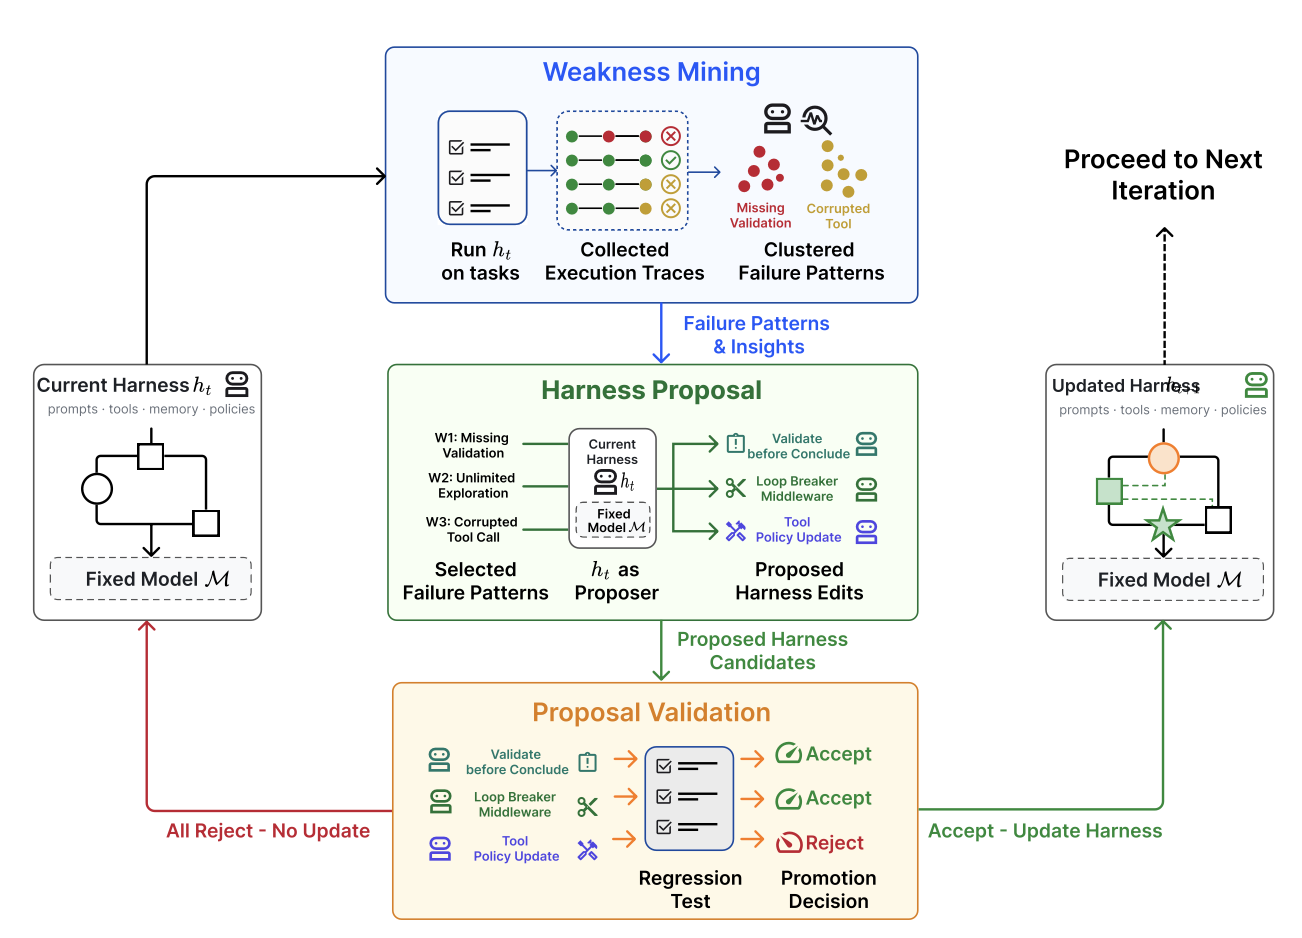
The Self-Harness loop consists of three stages:
- Weakness mining: cluster failures into verifier-grounded failure patterns.
- The current harness $h_t$ is used for task evaluation, and execution traces are collected for subsequent analysis.
- Be aware that two runs may appear to share the same verifier outcome in the surface-level error logs (for example, a timeout or a missing artifact) while arising from different underlying causal mechanisms. Therefore, to uncover root causes, we need a rich failure record that includes the terminal verifier-level cause, the causal status of the relevant agent behavior, and the abstract agent mechanism revealed by the trace.
- Harness proposal: propose bounded harness edits based on mined failure patterns.
- The same model is invoked under $h_t$ in the role of a proposer.
- The model receives a bounded proposal context consisting of: (1) the editable surfaces of the current harness, (2) the verifier-grounded failure patterns from the evaluation system, (3) records of passing behaviors that must be preserved, and (4) summaries of previously attempted edits.
- Harness edits should prioritize recurrent error patterns that are actionable (for example, not task-specific difficulty) and can be addressed through narrow, targeted changes.
- Harness edit candidates should be distinct and diverse.
- Proposal validation: validate and merge qualified edits to create a new harness $h_{t+1}$.
- Candidate edits are evaluated via regression tests on held-in $D_\text{in}$ (to test whether the weakness is resolved) and held-out $D_\text{out}$ (to check whether other, previously unknown issues have been introduced) splits.
- Candidates are accepted only if they introduce no regressions on both the held-in and held-out data.
- Accepted candidates are merged to update the harness to $h_{t+1}$, while rejected candidates are logged without modifying the active harness.
When running MiniMax M2.5, Qwen3.5-35B-A3B, and GLM-5 on Terminal-Bench-2, Self-Harness was shown to learn model-specific harness instructions that target different weaknesses in different base models and improve held-out pass rates.
This Self-harness line of work does raise a concern for me: if a program is permitted to edit the OS system, abstraction boundaries are broken. The editable surface must be designed appropriately, and permission control and security layers must live outside this loop. All the challenges around reward hacking still remain.
Agentic Harness Engineering (AHE; Lin et al. 2026) argues that the bottlenecks in harness evolution center on observability: when a rollout fails, we need to identify which component is responsible, and each edit should be grounded in evidence.
The framework forms a closed loop with three observability pillars:
- Component observability: every editable harness component has a representation in the file system, making the action space explicit and traceable.
- A harness contains 7 components: system prompt, tool description, tool implementation, middleware, skill, sub-agent configuration, and long-term memory.
- Each failure pattern is mapped to a single component so that edits can be more targeted.
- Experience observability: analyze and summarize large volumes of raw trajectories into a hierarchy of evidence and failure patterns.
- Each harness generates $k$ traces.
- An agent (the “Agent debugger”) analyzes the trajectories, each stored in a separate file, and produces a per-task analysis report describing the root cause of failure or success.
- All per-task reports are aggregated into a benchmark overview for the next step, and raw traces remain accessible when needed. This layered access structure is more token efficient.
- Decision observability: pair every edit with a prediction that can be validated in the next round.
- An agent (the “Evolve agent”) reads the repository, selects which component to edit, and then produces the edit along with the reasoning behind it.
- Each edit is a file-level, falsifiable claim that can be verified in the next round, subject to two constraints:
- (1) Edits are applied only to the harness workspace. The runs directory, tracer, verifier, and LLM configuration are read-only, which disables a set of reward-hacking tactics (e.g. disabling the verifier, swapping the model, or raising the reasoning budget). This ensures that every recorded gain remains attributable to harness edits.
- (2) Edits are evidence-driven and include a manifesto entry containing: the failure evidence name, the inferred root cause, the targeted fix, and a predicted impact that covers both expected fixes and at-risk regressions.
On Terminal-Bench-2, AHE outperformed human-designed harnesses (OpenCode, Terminus-2, Codex), except for the Hard tier, and also trailed a few other self-evolve baselines (ACE, TF-GRPO). The same frozen harness, without further evolution, transfers to SWE-bench-verified, suggesting that the evolved harness can encode engineering experience into harness components rather than performing benchmark-specific optimization.
Evolutionary Search
Evolutionary search is an optimization method inspired by natural selection (see my older post on evolutionary algorithm). It evolves a population of solutions by mutating them and retaining only those with high “fitness” within the population. Evolutionary search is particularly useful when (1) the search space is very large or irregularly shaped, and (2) direct gradient-based optimization is difficult, but evaluating candidate solutions is straightforward. Harness search appears to be well suited to this setting.
Evolutionary search has previously been applied to prompt engineering. Promptbreeder (Fernando et al. 2023) optimizes task-specific prompts using a rich set of mutation operations. Notably, the mutation prompts (that is, instructions to an LLM to mutate a task prompt) are themselves improved through evolution. GEPA (Agrawal et al. 2025) combines reflection-based prompting with evolutionary search, using natural-language reflection over trial-and-error trajectories to propose prompt updates.
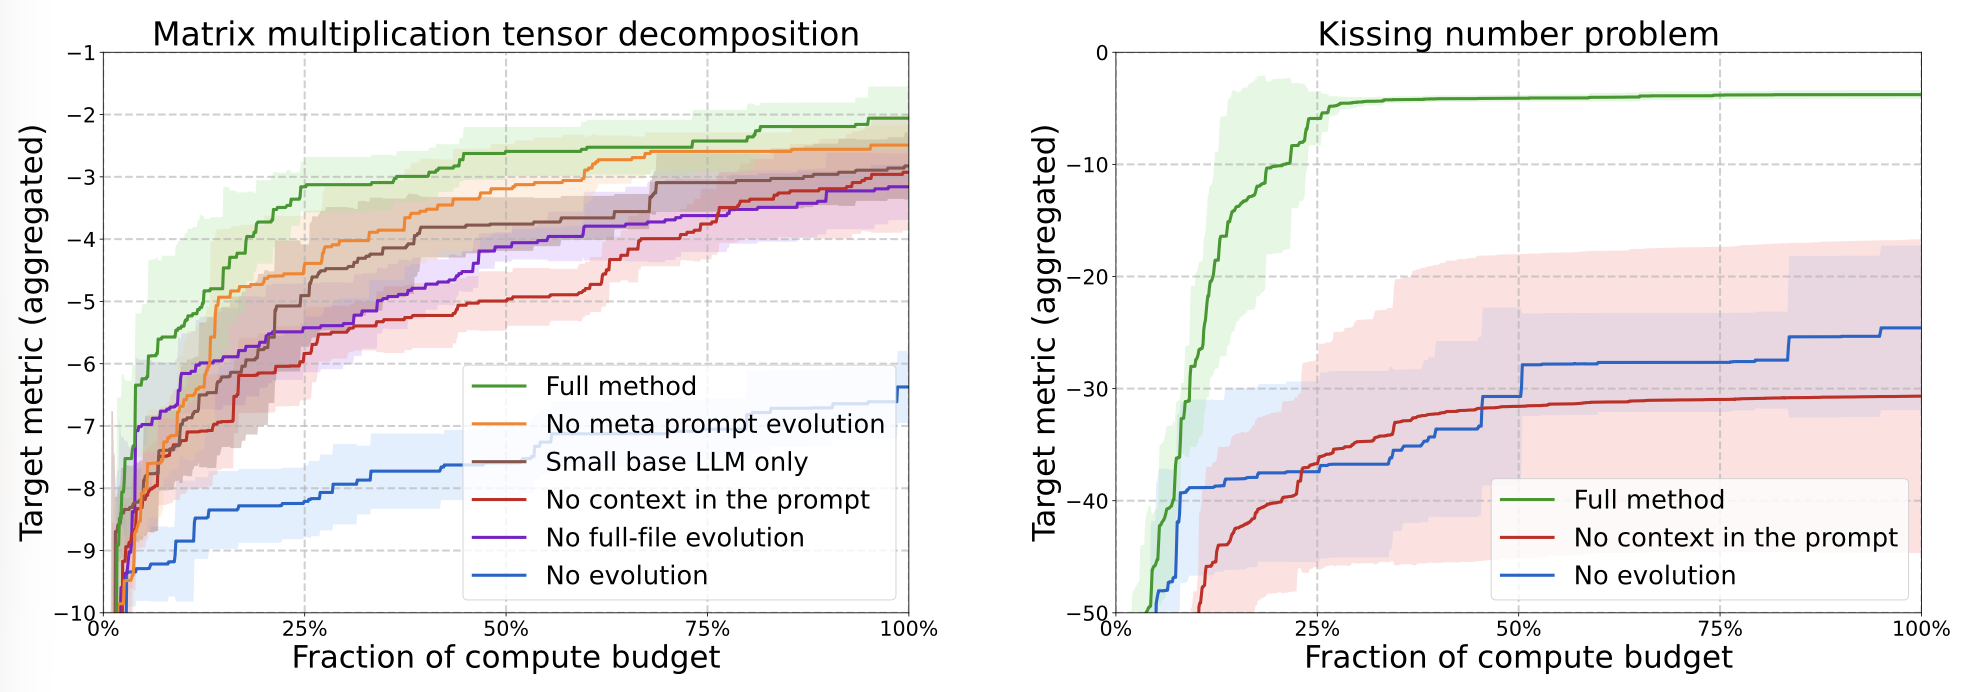
Novikov et al. (2025) introduced AlphaEvolve, an evolutionary search system for coding agents. It maintains a pool of candidate programs and prompts frozen LLMs to generate diffs that improve them. As the system repeatedly evaluates child programs and retains successful ones, it discovers better solutions over time.
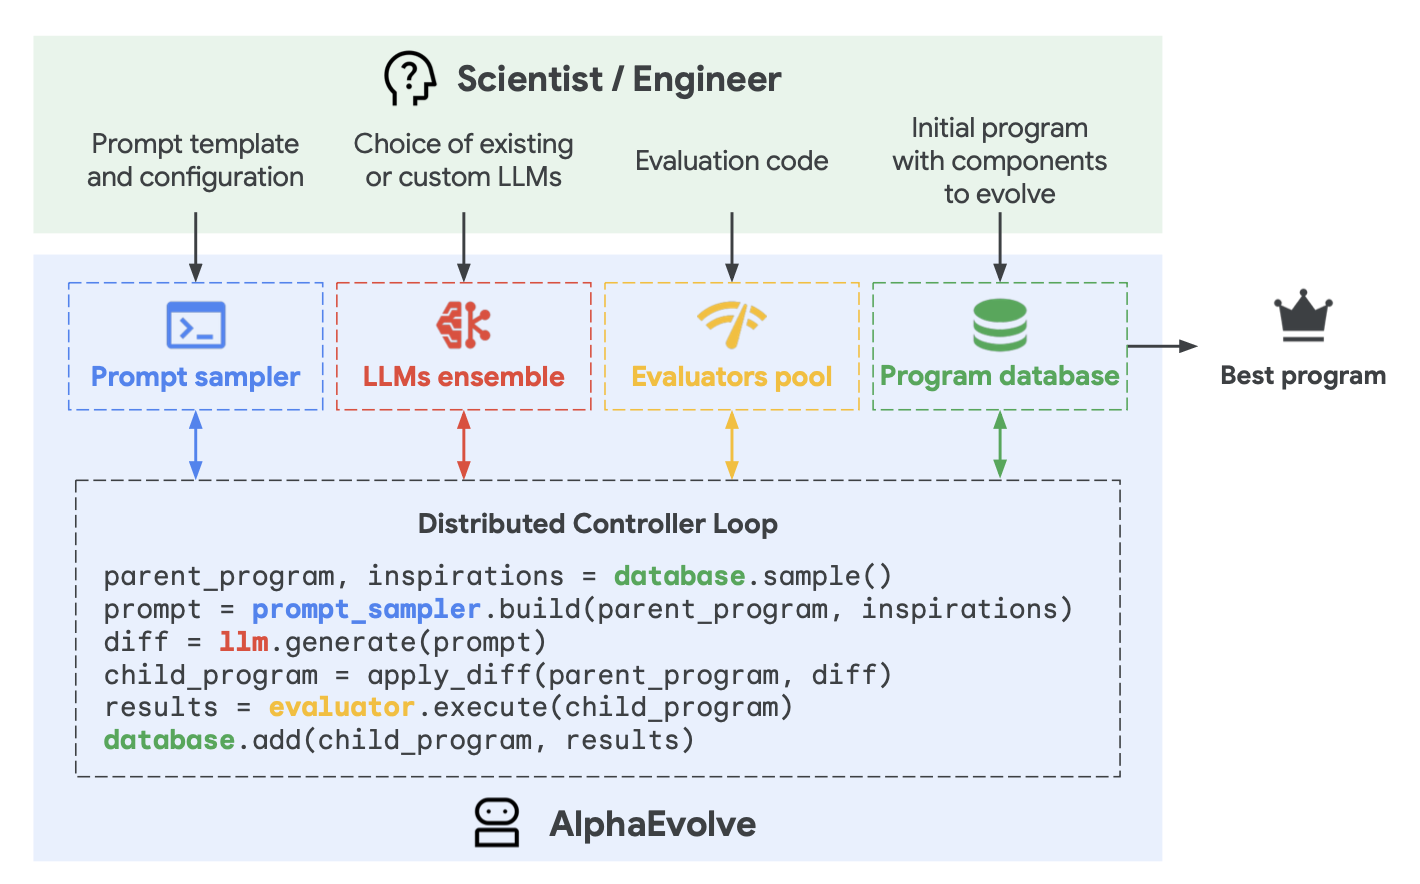
Several design details are important in AlphaEvolve:
- The prompt includes parent programs, results, instructions, and occasionally meta information.
- The coding agent can access the full repository, but regions intended for improvement are explicitly marked with
# EVOLVE-BLOCK-STARTand# EVOLVE-BLOCK-END. - The meta-prompt co-evolves with instructions and context as suggested by the LLM, in the same spirit as evolving the solution programs.
Ablations demonstrate the contributions of the evolution procedure, prompt context, meta-prompts, full-file evolution, and the use of stronger LLMs.
More recent variants include ThetaEvolve (Wang et al. 2025), which combines evolutionary search with RL and in-context learning, and DemoEvolve (Che, et al. 2026), which augments the self-rollout archive with human expert demonstrations as reference experience for harness-level diagnosis and editing. ShinkaEvolve (Lange et al. 2025), by contrast, introduced three new components to improve LLM sampling efficiency:
- More sample-efficient exploration by designing parent sampling to balance performance rank and offspring count.
- Code-novelty rejection sampling by discarding candidates that are too similar to the existing population based on embedding-based cosine similarity.
- Identifying useful patterns in successful solutions in a meta-scratchpad to guide future mutation.
Unlike the methods above, which focus on improving solutions, the Darwin Gödel Machine (DGM; Zhang et al. 2025) explicitly targets the evolution of an editable harness-code repository using an LLM-based coding agent. Specifically, the agent is allowed to modify its own harness. Follow-up work on Hyperagents (Zhang et al. 2026) introduced a meta-agent that controls how to modify existing task agents to create new ones.
- Start with one coding agent in the pool.
- In each iteration, select one parent with probability proportional to its performance and inversely proportional to the number of children it has, then modify it and branch off to produce new agents.
- The selected parent agent examines its own benchmark evaluation log and then proposes improvements to its own harness codebase to produce a new version of the coding agent. Code editing is implemented with two basic tools: (1) bash (args:
<bash_command>) and (2) editor (args:view/create/edit <file_path>). - Evaluate the new coding agents, and add back into the pool only those with sufficiently high performance.
- Repeat steps 2-4 until some stopping criteria are met.
DGM is harness evolution under a fixed model. In experiments using Claude 3.5 Sonnet as the base LLM and simple initial harness configurations, the agents discovered by DGM are comparable to, or outperform, handcrafted agents on SWE-bench Verified (20% to 50%) and Polyglot (14.2% to 30.7%).
This family of methods tends to work well when candidate solutions are automatically evaluable and fitness is easy to quantify, such as matrix multiplication, GPU kernel optimization, algorithm contests, and datacenter scheduling. It struggles in domains where evaluation is slow, ambiguous, or largely heuristic. Compute efficiency and the overall effectiveness of evolution are also continuing concerns.
Joint Optimization with Model Weights
Harness evolution modifies the non-parametric system surrounding the model. For full self-improvement, the model may also be allowed to update its own weights in parallel. Such weight updates could be implemented via improvements to the model training pipeline or through continual learning at test time. Continual learning is substantial enough to warrant its own post in the future.
SIA (Hebbar et al. 2026) is an early effort to combine harness improvement and model-parameter updates within a single optimization loop. The design includes three components:
- Meta-Agent: proposes the initial harness.
- Task-Specific Agent: executes the task.
- Feedback-Agent: decides whether to update the harness or the model weights based on recent trajectories.
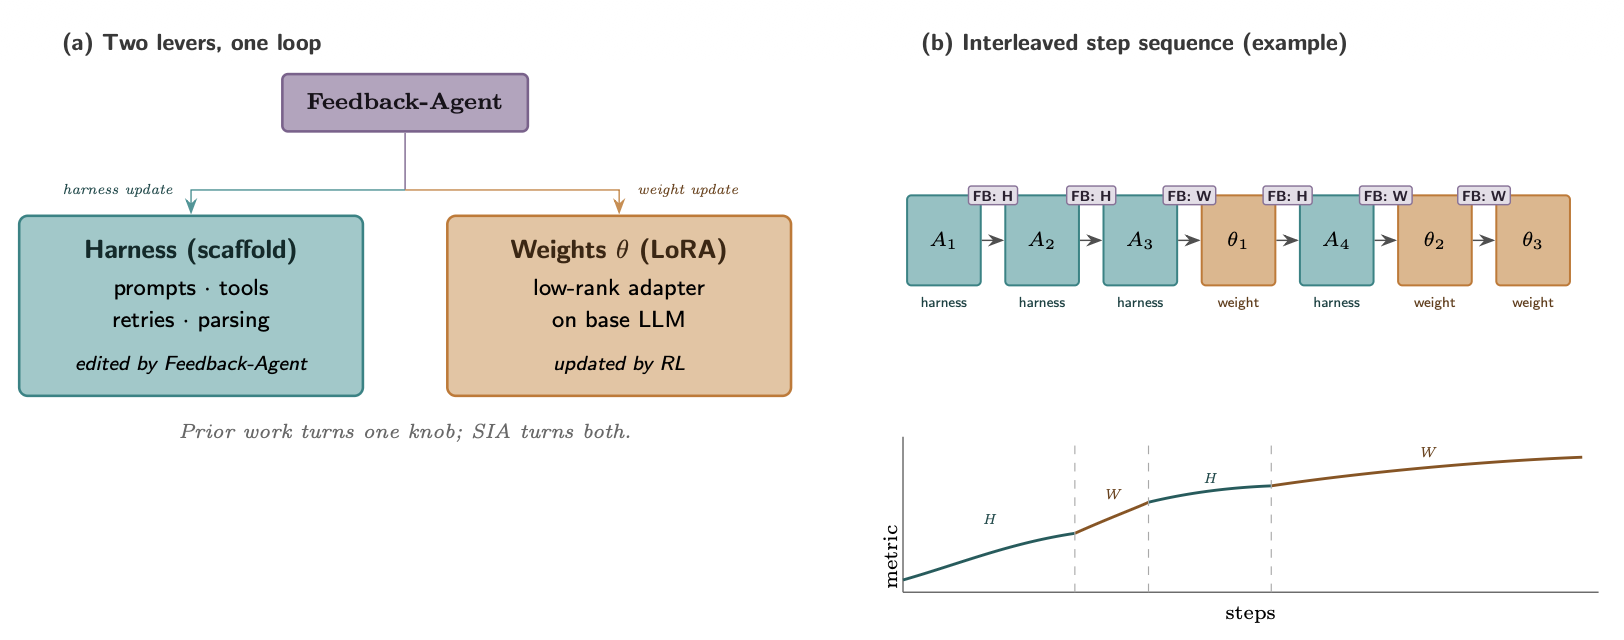
SIA’s experiments include several confounding choices that make the results difficult to interpret. For example, the task-specific agent is much weaker than the models used for the Meta-Agent and Feedback-Agent (gpt-oss-120b vs Claude Sonnet 4.6), and the baselines are too weak to provide a clean cross-reference against related methods. I find the direction interesting, but the evidence is provisional. Many challenges, including training stability and the Goodhart effect, also remain open.
Continual Harness (Karten et al. 2026) studies a long-horizon gameplay setting, combining harness updates with co-learning a policy model by distilling labels from a strong teacher model on low-reward trajectories.
Future Challenges
The AI Scientist line of work provides a strong demonstration that an expert-designed harness can coordinate a large portion of an auto-research loop, evaluated in the form of writing research papers. However, producing papers is not the same as making scientific discoveries. A system can generate a plausible manuscript while still including fabricated citations, implementation drift, or weak experimental results.
Trehan & Chopra (2026) tested whether LLMs can progress from a research idea to a paper with minimal scaffolding and basic tools (that is, read_file, write_file, llm_search, list_files). Each idea was assigned a dedicated workspace where agents could generate and read documents as part of the context. They ran experiments in three domains (world models, multi-agent RL, AI safety & alignment), with each domain containing 45-50 high-quality seed documents intended to inspire new ideas. Human experts selected only four ideas to proceed through the full pipeline, and only one was fully executed into a paper. They identified six recurring failure modes:
- Bias toward training-data defaults: using old libraries, stale commands, standard formats, or assumptions that are not grounded in the actual repository or dataset.
- Implementation drift under execution pressure: when implementation becomes technically complex, the model may gravitate toward a simpler, common solution instead of the proposed method.
- Memory and context degradation: long-horizon projects lose critical details unless logs are recorded as persistent artifacts.
- Over-optimism: the model claims success despite noisy or failed experiments, similar to the “p-hacking and eureka-ing” pattern observed by Bubeck et al. (2025), where models may introduce “numerical duct tape” and declare victory while the signals remain noise.
- Insufficient domain intelligence: the model lacks tacit craft knowledge, such as predicting implementation complexity, judging whether an experimental result is plausible, or knowing which baselines matter.
- Weak scientific taste: experiments may be runnable but fail to address the right question.
Progress toward full RSI has been real, but several bottlenecks still remain.
1. Weak and fuzzy evaluators. Many research claims lack a fast, precise verifier, and the same limitation applies to many real-world tasks. Current self-improvement loops work best when evaluation metrics are measurable and objective, analogous to how RL works.
Research taste, novelty, and long-term scientific value are far harder to measure. For instance, research taste often blends problem framing, experimental design, and judgment about which surprising results warrant pursuit and which failure cases merit retries.
2. Context and memory lifecycle. Memory demands grow as AI agents become more autonomous and independent. A useful harness must manage context and memory to compensate for current limitations in long-context generation while still maximizing success on long-horizon tasks. Since humans can maintain memory throughout our lifetime, I see an analogy here: context engineering will, and should, become a core component of intelligence rather than remaining solely a software system layer concern.
3. Negative results. Researchers are incentivized to publish successful outcomes, which biases the literature toward successes. LLMs trained on vast quantities of data (mostly human created, at least for now, lol) may struggle to determine when to abandon a hypothesis, report a negative result, or even acknowledge a failure, due to the imbalance between success and failure cases in the data. A research harness should make failed attempts easy to preserve, since learning from failure is one of the best ways to reduce the task search space.
4. Diversity collapse. Evolutionary and RL loops tend to exploit known high-reward patterns. We need mechanisms that prevent the population from collapsing into variants of the same solution. This is especially important for open-ended research, where the best path may initially appear worse under the current evaluator.
5. Reward hacking. A self-improvement loop optimizes whichever signal it is given. If the reward comes from unit tests, the agent may overfit to those tests. If it comes from a judge model, it may learn reward-hacking strategies specific to that judge. If it comes from benchmark scores, it may exploit benchmark artifacts.
The evaluator and permission control should likely remain outside the loop that evolves the harness, with held-out tests, trace audits, and human review at decision points that matter. How much oversight can be scaled and automated remains an open research area.
6. Long-term success. An extrinsic optimization loop operates on rewards that sit outside individual rollouts we can simulate in a training sandbox.
Consider coding agents as an example. They already increase daily productivity in software engineering, but many optimization objectives remain too short term. A coding agent can often complete the immediate task, yet it is less clear how it should safeguard the long-term health of a repository collectively maintained by hundreds or thousands of engineers. Standard sandbox-based RLVR-style training rarely captures maintainability, ownership boundaries, migration cost, backward compatibility, or future debugging burden.
7. The role of humans. Humans should move up the stack rather than being removed from the loop. In practice, this means humans should provide oversight at the right time and at the right abstraction level, and system design should explicitly plan when and how to establish these touch points.
Many of the challenges above require human feedback and steering. After all, we are building technology for a better future for humanity, not the other way around.
Citation
Please cite this work as:
Weng, Lilian. “Harness Engineering for Self-Improvement”. Lil’Log (Jul 2026). https://lilianweng.github.io/posts/2026-07-04-harness/
Or use the BibTeX citation:
@article{weng2026harness,
  title = {Harness Engineering for Self-Improvement},
  author = {Weng, Lilian},
  journal = {lilianweng.github.io},
  year = {2026},
  month = {July},
  url = "https://lilianweng.github.io/posts/2026-07-04-harness/"
}
Appendix: Some useful benchmarks
- PaperBench: replicate 20 ICML 2024 Spotlight and Oral papers from scratch, including understanding paper contributions, developing a codebase, and successfully executing experiments.
- Each replication task is decomposed into smaller, individually gradable tasks.
- 8,316 rubrics in total, co-developed with the paper authors.
- The best model at the time (
Claude 3.5 Sonnet, ~21%) does not outperform ML PhDs. - Includes PaperBench, PaperBench Code-Dev (a lighter version), and JudgeEval.
- CORE-Bench: evaluate computational reproducibility of published research.
- 270 tasks based on 90 scientific papers across computer science, social science, and medicine.
- Tasks involve reproducing results from provided code and data.
- Includes multiple difficulty levels and both language-only and vision-language tasks.
- The best reported agent at the time (
GPT-4oandGPT-4o-mini) achieved only 21% accuracy on the hardest task.
- ScienceAgentBench: evaluate LLM agents for data-driven scientific discovery.
- Extracts 102 tasks from 44 peer-reviewed publications in four disciplines (math, chemistry, biology, geography).
- Covers basic data-science tasks in these domains: data processing, model development, data analysis, and information visualization.
- RE-Bench: evaluate frontier AI agents on realistic ML research-engineering envs against human experts.
- 7 challenging, open-ended ML research-engineering environments.
- Each environment = (scoring function, starting solution, reference solution); each can be run with 8 or fewer H100 GPUs.
- Examples: optimize a kernel, run a scaling-law experiment, fix an embedding, fine-tune GPT-2 for QA, etc.
- Includes data from 71 eight-hour attempts by 61 distinct human experts.
- Human experts achieved non-zero score in 82% of 8-hour attempts; 24% matched or exceeded strong reference solutions.
- Best AI agents scored 4× higher than humans at a 2-hour budget, but humans had better returns to longer budgets and exceeded agents at 8-hour and 32-hour settings.
- MLE-bench: evaluate ML engineering agents on offline Kaggle competitions.
- Contains 75 ML-engineering competitions curated from Kaggle.
- Tests training models, preparing datasets, running experiments, and submitting predictions to grading scripts.
- Uses Kaggle public leaderboards as human baselines.
- Best setup in the paper,
o1-previewwith AIDE scaffolding, reached at least Kaggle bronze-medal level in 16.9% of competitions. - Includes resource-scaling and contamination analyses.
- KernelBench: evaluate correctness and speed for generated GPU kernels.
- 250 PyTorch tasks to evaluate whether LLM can write fast and correct kernels.
- The evaluation metric fast_p = the percentage of generated kernels that are correct and faster than baseline.
References
[1] Good, I. J. “Speculations Concerning the First Ultraintelligent Machine.” Advances in Computers, 6:31–88, 1965.
[2] Yudkowsky, Eliezer. “Recursive Self-Improvement.” LessWrong, 2008.
[3] Choi, et al. “Anchored Self-Play for Code Repair.” ICML 2026.
[4] Zhao, et al. “Absolute Zero: Reinforced Self-play Reasoning with Zero Data.” arXiv preprint arXiv:2505.03335, 2025.
[5] Yuan, et al. “Self-Rewarding Language Models.” arXiv preprint arXiv:2401.10020, 2024.
[6] Chen, et al. “Self-Play Fine-Tuning Converts Weak Language Models to Strong Language Models.” ICML 2024.
[7] Zhang, et al. “Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models.” ICLR 2026.
[8] Ye, et al. “Meta Context Engineering via Agentic Skill Evolution.” arXiv preprint arXiv:2601.21557, 2026.
[9] Lee, et al. “Meta-Harness: End-to-End Optimization of Model Harnesses.” arXiv preprint arXiv:2603.28052, 2026.
[10] Lu, et al. “Towards end-to-end automation of AI research.” Nature, 651:914–919, 2026.
[11] Meng, et al. “ScientistOne: Towards Human-Level Autonomous Research via Chain-of-Evidence.” arXiv preprint arXiv:2605.26340, 2026.
[12] Kulikov, et al. “Autodata: An agentic data scientist to create high quality synthetic data.” arXiv preprint arXiv:2606.25996, 2026.
[13] Hu, Lu, and Clune. “Automated Design of Agentic Systems.” ICLR 2025.
[14] Madaan, et al. “Self-Refine: Iterative Refinement with Self-Feedback.” NeurIPS 2023.
[15] Zhang, et al. “AFlow: Automating Agentic Workflow Generation.” ICLR 2025.
[16] Zelikman, et al. “Self-Taught Optimizer (STOP): Recursively Self-Improving Code Generation.” COLM 2024.
[17] Zhang, et al. “Self-Harness: Harnesses That Improve Themselves.” arXiv preprint arXiv:2606.09498, 2026.
[18] Fernando, et al. “Promptbreeder: Self-Referential Self-Improvement Via Prompt Evolution.” arXiv preprint arXiv:2309.16797, 2023.
[19] Agrawal, A. et al. “GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning.” arXiv preprint arXiv:2507.19457, 2025.
[20] Novikov, et al. “AlphaEvolve: A coding agent for scientific and algorithmic discovery.” arXiv preprint arXiv:2506.13131, 2025.
[21] Lange, Imajuku, and Cetin. “ShinkaEvolve: Towards Open-Ended And Sample-Efficient Program Evolution.” arXiv preprint arXiv:2509.19349, 2025.
[22] Wang, et al. “ThetaEvolve: Test-time Learning on Open Problems.” arXiv preprint arXiv:2511.23473, 2025.
[23] Zhang, et al. “Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents.” arXiv preprint arXiv:2505.22954, 2025.
[24] Zhang, et al. “Hyperagents.” arXiv preprint arXiv:2603.19461, 2026.
[25] Yuksekgonul, et al. “Learning to Discover at Test Time.” arXiv preprint arXiv:2601.16175, 2026.
[26] Riaz, et al. “Epistemic Uncertainty for Test-Time Discovery.” arXiv preprint arXiv:2605.11328, 2026.
[27] Hebbar, et al. “SIA: Self Improving AI with Harness & Weight Updates.” arXiv preprint arXiv:2605.27276, 2026.
[28] Trehan and Chopra. “Why LLMs Aren’t Scientists Yet: Lessons from Four Autonomous Research Attempts.” arXiv preprint arXiv:2601.03315, 2026.
[29] Bubeck, et al. “Early science acceleration experiments with GPT-5.” arXiv preprint arXiv:2511.16072, 2025.
[30] Starace, et al. “PaperBench: Evaluating AI’s Ability to Replicate AI Research.” ICML 2025.
[31] Wijk, et al. “RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts.” ICML 2025.
[32] Chan, et al. “MLE-bench: Evaluating Machine Learning Agents on Machine Learning Engineering.” arXiv preprint arXiv:2410.07095, 2024.
[33] Chen, et al. “ScienceAgentBench: Toward Rigorous Assessment of Language Agents for Data-Driven Scientific Discovery.” ICLR 2025.
[34] Siegel, et al. “CORE-Bench: Fostering the Credibility of Published Research Through a Computational Reproducibility Agent Benchmark.” TMLR 2024.
[35] Ouyang, et al. “KernelBench: Can LLMs Write Efficient GPU Kernels?” arXiv preprint arXiv:2502.10517, 2025.
[36] Lin, et al. “Harness Updating Is Not Harness Benefit: Disentangling Evolution Capabilities in Self-Evolving LLM Agents.” arXiv preprint arXiv:2605.30621, 2026.
[37] Lin, et al. “Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses.” arXiv preprint arXiv:2604.25850, 2026.
[38] Karten, et al. “Continual Harness: Online Adaptation for Self-Improving Foundation Agents.” arXiv preprint arXiv:2605.09998, 2026.
[39] Che, et al. “DemoEvolve: Overcoming Sparse Feedback in Agentic Harness Evolution with Demonstrations.” arXiv preprint arXiv:2605.24539, 2026.